
Self-hosted first
Your agent memory stays on your servers. No data leaves your infrastructure. Full control over storage, retention and access.
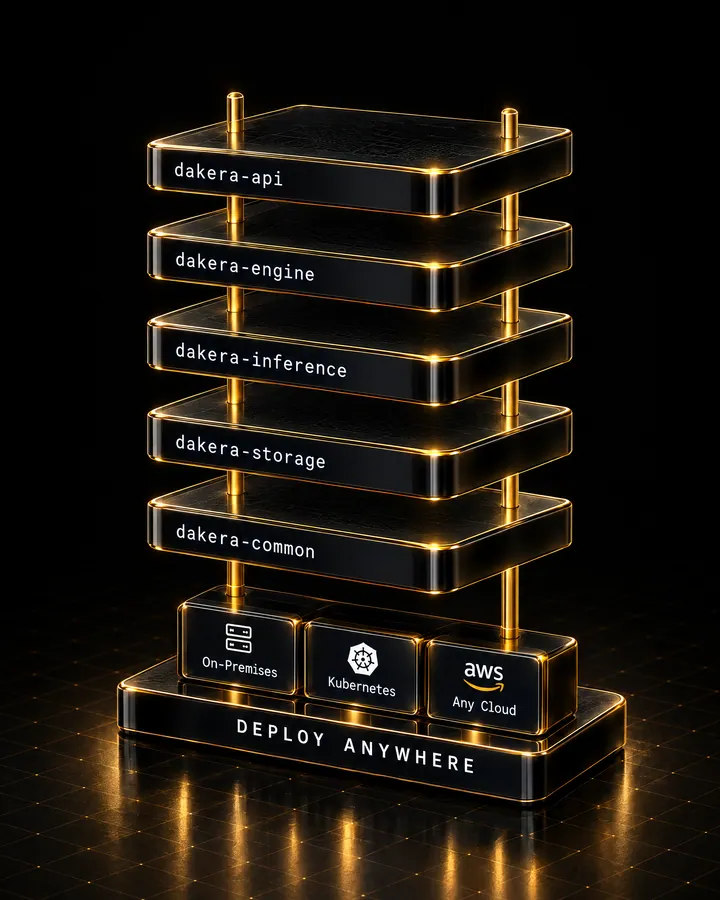

Dakera builds open-core memory infrastructure so AI agents can remember context across conversations, sessions and teams, without sending data to third parties.

AI agents are getting smarter at reasoning, but they keep forgetting. Every time a conversation ends, the context is lost. Teams waste time re-explaining preferences. Customer support bots ask the same questions twice. Multi-agent systems can't share knowledge.
We believe memory is the missing layer in the AI stack. Not a simple key-value store, but real memory that understands temporal relationships, supports hybrid retrieval and builds knowledge graphs automatically.
Dakera is a single Rust binary that runs on your infrastructure. No external APIs, no embedding service, no separate database to manage: the ONNX models ship in the Docker image. Start the server, connect your agent or AI client, and it starts remembering. Most teams are running in under five minutes.
Read the quickstartA single binary handles the whole memory lifecycle, from storing a memory to recalling and decaying it, with no external services.
Your agents connect through
A memory arrives with its metadata and is embedded on the machine, then indexed by every engine at once.
The query is classified, searched in parallel, fused and reranked into one ordered answer.
Importance-weighted scoring keeps what the agent keeps using and lets the rest fall away.
Kept in one process, on your disk
Your agent memory stays on your servers. No data leaves your infrastructure. Full control over storage, retention and access.
One Rust binary. No Redis, no Postgres, no external embedding API. Storage, embeddings, retrieval and the knowledge graph are built in.
The memory engine is proprietary and free to self-host. SDKs for Python, JavaScript, Rust and Go are MIT-licensed. Build on Dakera without vendor lock-in.
88.2%Recall@20 on LoCoMo
88.2% Recall@20 on LoCoMo, the standard long-conversation memory benchmark. Built for concurrent agents, with encryption at rest, scoped API keys and metrics.
Not a tool for demos. Dakera is built for developers deploying intelligent agents into production who need real infrastructure underneath.
Read the deployment guide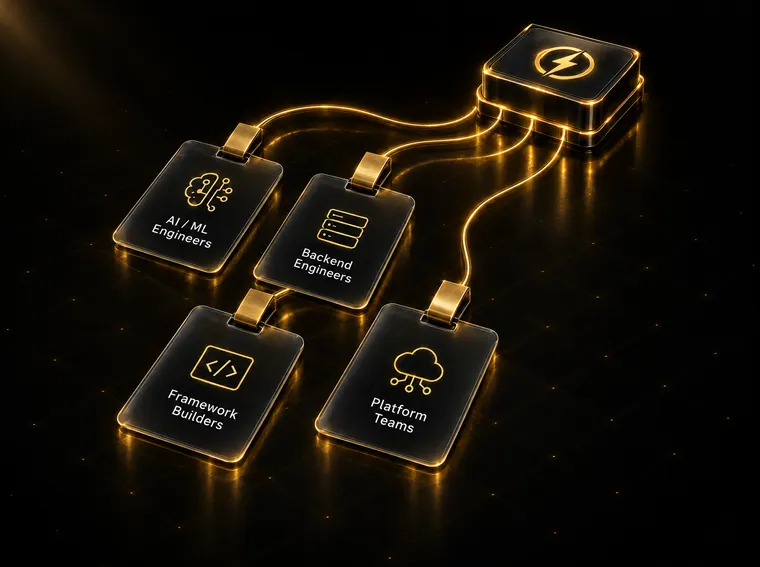

AI and ML engineers
You ship LangChain or AutoGen agents that need to remember state across thousands of sessions, without duct-taping Redis, Pinecone and a custom decay script together.
Backend engineers
You are adding an AI feature to an existing product and need a reliable memory layer, not a research project. You care about latency, auth, multi-tenancy and zero new infra to maintain.
Framework builders
You build tools on top of agent frameworks and need a memory backend that works across all of them: consistent API, framework-agnostic and fast enough for tool-calling loops.
Platform teams
You run the platform that dozens of internal teams build agents on. You need multi-tenancy, observability, horizontal scaling and security posture, not a managed service with opaque pricing.
Dakera is built by infrastructure engineers who've shipped ML pipelines, vector search systems and distributed data stores at scale, and hit the same wall every time: agents that can't remember. We spent too many hours duct-taping Redis, Pinecone and custom TTL scripts together and decided to build the thing we wished existed.
Our background is in low-level systems engineering: Rust, storage engines and retrieval algorithms. Dakera's 88.2% LoCoMo Recall@20 comes from doing retrieval correctly at the engine level (hybrid BM25 and vector fusion, importance decay, on-device ONNX inference), not from bolting LLM reranking onto a vector store as an afterthought.
We believe the best infrastructure is invisible: it just works. Dakera should be as easy to set up as pulling a Docker image, and as reliable as the filesystem underneath it. No managed services, no opaque pricing, no data leaving your network.
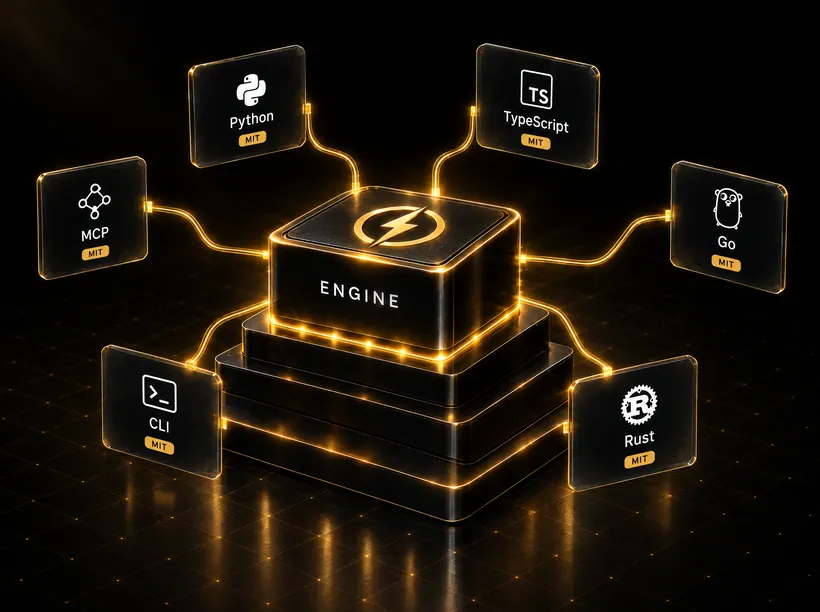

We open everything you need to integrate and keep what makes us fast. You can self-host the engine: the binary is yours to run on your own infrastructure, with no outbound user data and no external dependencies. What's closed is the source code, not your right to deploy it.
One binary, no external services. Pull the Docker image, set your API key, and your agents start remembering.